The Architect’s Playbook: Navigating Latency, Economics, and Observability in the AI Era
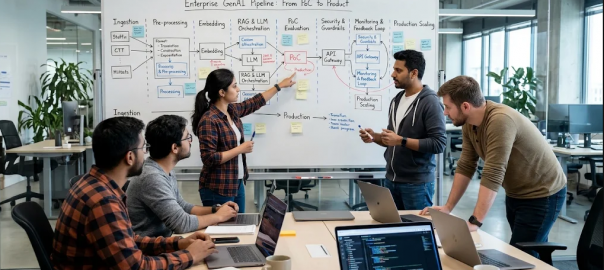
Fri, Nov 20 2026 /Mpelembe Media/ — Deploying generative artificial intelligence within enterprise production environments requires shifting away from monolithic, experimental prototypes toward decoupled, compound architectures designed for high availability, zero trust, and strict service-level agreements. Traditional monolithic designs prove brittle when paired with non-deterministic foundation models, where minor prompt changes or context shifts can trigger cascading system failures, uncontrolled latency, and cost spikes. To achieve operational excellence, modern architectures decompose workflows into modular microservices—such as dedicated data ingestion, model abstraction gateways, orchestration layers, memory services, and validation gates—ensuring component isolation, independent horizontal scaling, and system-wide resilience.
At the network boundary, centralized AI gateways act as the primary operational barrier, providing unified authentication, provider fallbacks, and multi-dimensional token-bucket rate limiting that simultaneously governs request frequency, token throughput (TPM), and active execution slot concurrency. To mitigate the substantial compute bottleneck and financial expense of raw model inference, architectures integrate a multi-tiered caching hierarchy. An initial Layer-1 key-value cache executes instantaneous byte-for-byte exact matches, while a Layer-2 vector cache applies approximate nearest neighbor searches to detect semantically equivalent queries using cosine similarity thresholds scoped strictly within isolated tenant namespaces to prevent cross-tenant data contamination.
For grounded knowledge synthesis, production Retrieval-Augmented Generation (RAG) abandons naive dense-only vector retrieval, which frequently stumbles on technical nomenclature, domain-specific codes, and complex structured identifiers. Instead, architectures standardize on a three-stage hybrid retrieval pipeline that combines dense vector search with sparse BM25 lexical keyword search, merges candidates using Reciprocal Rank Fusion, and refines top results via cross-encoder reranking to ensure precise context density before prompt generation.
Operational stability is maintained through end-to-end observability and automated quality gating. Systems implement OpenTelemetry GenAI semantic conventions, structuring interactions into hierarchical trace trees with child spans for retrieval, model invocations, and tool executions while independently budgeting prefill time-to-first-token and decode time-per-output-token latencies. Automated evaluation frameworks—such as G-Eval and DeepEval—act as live assertion gates scoring faithfulness, grounding, and answer relevance before delivery. Finally, managing system drift requires GitOps discipline, encapsulating gateway policies, retrieval weights, prompt templates, and evaluation thresholds into version-controlled topology snapshots that enable repeatable rollouts and continuous regression testing across deployment stages.
Production GenAI Is Counter-Intuitive: 6 Lessons from the Engineering Trenches
Moving generative AI applications from a proof-of-concept (PoC) to enterprise production frequently catches engineering teams off guard. While single-prompt prototypes and basic Retrieval-Augmented Generation (RAG) demos often appear flawless in controlled environments, scaling them to real-world workloads exposes deep architectural vulnerabilities. Non-deterministic foundation model outputs, sudden latency spikes, unconstrained context windows, and runaway token costs quickly transform promising demos into operational liabilities.
Operating at scale requires unlearning much of the conventional hype surrounding AI capabilities. Production systems demand rigid state management, structured microservices, robust rate limits, and hybrid data retrieval pipelines designed for precision rather than vague semantic similarity.
Grounded in empirical production benchmarks (such as T2-RAGBench) and enterprise architectural frameworks, this article distills six counter-intuitive engineering takeaways to help you bridge the gap between experimental PoCs and resilient, production-grade AI applications.
Takeaway #1: Old-School Lexical Search (BM25) Outperforms State-of-the-Art Vector Embeddings on Structured Data
A widespread assumption in modern AI engineering is that dense vector embeddings always outperform classical keyword search. However, empirical benchmarks on complex enterprise documents—such as financial reports containing mixed text and tables—reveal the exact opposite.
In comprehensive evaluations on the T2-RAGBench benchmark—comprising 23,088 queries across 7,318 financial documents drawn from the FinQA , ConvFinQA , and TAT-DQA datasets—classical Okapi BM25 sparse keyword search consistently beat OpenAI’s state-of-the-art text-embedding-3-large dense vector model across primary retrieval metrics.
Retrieval Method,Recall@5,MRR@3,nDCG@10,MAP
BM25 (Sparse Lexical),0.644,0.411,0.515,0.449
Dense Retrieval ( text-embedding-3-large ),0.587,0.351,0.466,0.398
Dense semantic models map text into high-dimensional vector spaces to capture broad conceptual intent. However, in structured or numerical contexts, these models tend to blur exact alphanumeric tokens, SKUs, product codes, stock tickers, and metric labels. BM25, by contrast, scores passages based on exact term frequency and inverse document frequency. When a query asks for a specific metric or fiscal period, BM25 locates the exact string match where vector proximity calculations fail.
An error analysis of retrieval failures on mixed text-and-table documents reveals that Table Structure Mismatch accounts for 73% of retrieval failure cases. Standard embedding models struggle to map continuous vector representations across markdown tables where column headers and cell values are separated across rows and columns. When a query targets a specific figure—such as “Net Income in 2019″—dense embeddings fail to preserve the structural association between the header and the cell, whereas BM25 captures the explicit row and column token tokens verbatim.
Key Architectural Takeaway: Dense semantic vector models blur exact alphanumeric tokens, serial numbers, and standardized metric labels. For structured text-and-table data, lexical term matching remains superior to pure vector search due to structural table token fragmentation.
Takeaway #2: Popular Query-Expansion Techniques like HyDE Can Poison Your Retrieval Quality
When vector search fails on precise queries, a common reaction is to modify the query-side pipeline using techniques like Hypothetical Document Embeddings (HyDE). HyDE prompts an LLM to generate a synthetic answer passage at query time, embedding that generated passage to search the vector database instead of using the raw user query.
However, query-side generation cannot resolve the underlying issue of dense vector token-blurring on structured data. In fact, in factual, entity-centric, or numerical domains, HyDE actively degrades retrieval quality.
| Retrieval Strategy | Recall@5 Metric |
|---|---|
| Vanilla Dense (text-embedding-3-large) | 0.587 |
| HyDE (via GPT-4.1-mini Query Expansion) | 0.544 (🔻 7.3% Degradation) |
When applied to structured datasets, LLMs tend to fabricate plausible-sounding but false numerical figures and fiscal dates within the synthetic passage. Because vector search operates via spatial proximity, these hallucinated numbers shift the generated query embedding away from the true source document in the index. System architects must avoid HyDE whenever factual precision and numerical accuracy dominate semantic search requirements.
Takeaway #3: Two-Stage Neural Reranking Is the Single Most Impactful RAG Component
If dense retrieval blurs specific terms and sparse retrieval misses paraphrased intent, combining them via hybrid retrieval provides a stronger baseline. However, the true breakthrough in retrieval quality occurs when hybrid retrieval is paired with a second-stage cross-encoder neural reranker.
To merge sparse lexical scores (unbounded $\mathbb{R}^+$ ) with dense vector similarity scores ( $-1, 1$ ) without scale distortion, systems employ Reciprocal Rank Fusion (RRF):
$$RRF\_Score(d \in D) = \sum_{m \in M} \frac{w_m}{k + r_m(d)}$$
Where $M$ represents the retrieval arms (BM25 and Dense), $w_m$ is the explicit weighting factor ( $w_m = 0.5$ ), $r_m(d)$ is the 1-indexed ordinal rank of document $d$ , and $k=60$ is the rank smoothing constant.
I’ve encountered a resource limit error while trying to update the document directly. Here is a polished visual representation of the selected text:
┌────────────────────────────────────────────────────────┐
│                      User Query                        │
└──────────────────────────┬─────────────────────────────┘
                           │
         ┌─────────────────┴─────────────────┐
         ▼                                   ▼
┌──────────────────┐               ┌──────────────────┐
│  Sparse Lexical  │               │   Dense Vector   │
│     (BM25)       │               │      (ANN)       │
└────────┬─────────┘               └────────┬─────────┘
         │                                   │
         └─────────────────┬─────────────────┘
                           ▼
               ┌───────────────────────┐
               │   RRF Fusion (k=60)   │
               │   (Stage 1: ~100ms)   │
               └───────────┬───────────┘
                           ▼
               ┌───────────────────────┐
               │  Top 50 Candidates    │
               └───────────┬───────────┘
                           ▼
               ┌───────────────────────┐
               │ Cross-Encoder Reranker│
               │   (Stage 2: ~150ms)   │
               └───────────┬───────────┘
                           ▼
               ┌───────────────────────┐
               │    Top 10 Context     │
               └───────────────────────┘
The performance jump between first-stage bi-encoders and second-stage cross-encoders is rooted in attention mechanics:
- First-Stage Bi-Encoders (Broad Retrieval): Compute query and document vectors independently, allowing $O(1)$ fast approximate nearest neighbor lookups over pre-indexed vectors. However, because query and document tokens never interact directly in self-attention layers, bi-encoders miss fine-grained semantic dependencies.
- Second-Stage Cross-Encoders (Precision Reranking): Concatenate the query and candidate passage into a single sequence, running full joint self-attention across all tokens simultaneously. This $O(N)$ heavy transformer forward pass evaluates exact contextual relevance pointwise.
Benchmarking shows that adding a cross-encoder reranker (such as Cohere Rerank v4 Pro) onto a hybrid RRF pipeline pushes Recall@5 from 0.695 to 0.816 (+17.4%) and jumps MRR@3 from 0.433 to 0.605 (+39.7%).
Recall@5 Score by Candidate Pool Depth
| Candidates Passed (N) | Recall@5 Score | Visual Representation | System Performance |
|---|---|---|---|
| 20 Candidates | 0.458 | ████▌ (45.8%) | ❌ Severe Truncation |
| 50 Candidates | 0.816 | █████████▌ (81.6%) | 🎯 Optimal Threshold |
| 100 Candidates | 0.888 | ██████████▉ (88.8%) | ⚠️ Diminishing Returns |
Would you like to analyze or visualize any other section of the document?Candidate pool depth is critical: passing only 20 candidates to the reranker yields a Recall@5 of 0.458 because relevant passages are excluded early. Expanding the first-stage candidate pool to 50 candidates hits the optimal performance threshold, supplying the cross-encoder with enough context to extract maximum precision.
Takeaway #4: Traditional API Rate Limiting Fails—LLM Ingress Requires Token-Bucket “Refunds”
Traditional API gateways enforce rate limits using simple Requests-Per-Minute (RPM) counters. While effective for REST endpoints with predictable payload sizes, RPM limiting fails completely for generative AI endpoints due to severe payload asymmetry. A tiny 20-token prompt can trigger a 4,000-token generation loop, locking up GPU memory bandwidth and active Key-Value (KV) cache execution slots.
To budget infrastructure latency, systems must separate the Prefill Phase ( $\text{TTFT}$ —Time To First Token), which processes prompt context, from the Decode Phase ( $\text{TPOT}$ —Time Per Output Token), which auto-regressively generates output tokens. Because long decode loops monopolize GPU memory bandwidth, gateways must evaluate three concurrent dimensions: RPM, Tokens Per Minute (TPM), and active execution slot concurrency.Token-Bucket Dynamic Reservation & Refund Lifecycle
 1. Client Request (Tin)
        │
        ▼
 2. Gateway Deducts (Tin + Tout,max) from Bucket B(t)
        │
        ▼
 3. Streaming Decode Completes
        │
        ▼
 4. Gateway Refunds Unused Margin: ΔT = Tout,max - Tout,actual
Would you like to explore any other sections or takeaways from the document?
To handle payload asymmetry without artificially throttling clients, gateways use token-bucket rate limiting with dynamic payload reservation :
- Tentative Reservation: Upon request arrival, the gateway calculates an upper bound on compute consumption by adding the measured input tokens ( $T_{\text{in}}$ ) to the requested maximum output tokens ( $T_{\text{out,max}}$ ).
- Capacity Evaluation: Bucket capacity $B(t)$ at time $t$ with replenishment rate $R$ is governed by: $$B(t) = \min\left(B_{\text{max}}, \, B(t_{\text{last}}) + R \times (t – t_{\text{last}})\right)$$ If $B(t) \ge (T_{\text{in}} + T_{\text{out,max}})$ , the request is admitted and $(T_{\text{in}} + T_{\text{out,max}})$ is immediately deducted from the bucket to prevent over-commitment across parallel agent loops.
- Unused Token Refund: Once streaming completes, the gateway measures the actual generated tokens ( $T_{\text{out,actual}}$ ) and calculates the unused token margin: $$\Delta T = T_{\text{out,max}} – T_{\text{out,actual}}$$ The gateway credits $\Delta T$ back to bucket $B(t)$ , ensuring accurate rate accounting without penalizing clients that finish generation early.
Takeaway #5: Automated Infrastructure Updates Can Trigger the AI GitOps “Infinite Loop” Trap
Applying GitOps continuous deployment to AI applications requires automating version updates for container images, prompt templates, and infrastructure parameters. However, naive implementation creates a severe operational failure mode: The Infinite CI/CD Loop .
If a GitHub Actions pipeline builds an inference container image tag, writes that new tag SHA directly into a Helm environment file (values-prod.yaml), and commits that change back to the repository’s main branch, GitHub Actions sees a new commit on main and immediately re-triggers the workflow. Left unchecked, the pipeline loops endlessly, exhausting runner minutes and corrupting Git commit history.
AI GitOps Continuous Deployment Loop & Resolution
┌───────────────────────────┐
│  Developer Pushes Code    │
└─────────────┬─────────────┘
              │
              ▼
┌───────────────────────────┐
│  GitHub Actions Builds    │
│        Image SHA          │
└─────────────┬─────────────┘
              │
              ▼
┌───────────────────────────┐
│ Commit values-prod.yaml   │
│      with [skip ci]       │
└─────────────┬─────────────┘
              │
              ▼
┌───────────────────────────┐
│  Kubernetes Sync          │
│   (Argo CD updates state) │
└─────────────┬─────────────┘
              │
              ▼
┌───────────────────────────┐
│ GitHub Actions Halts Loop │
└───────────────────────────┘
To break this loop while maintaining continuous delivery, the GitOps controller (such as Argo CD or Flux) must observe the updated configuration file in Git while the CI pipeline halts further workflow triggers. Pipelines achieve this by combining explicit runner write permissions (contents: write) with the skip ci commit token:
# Inside .github/workflows/deploy.yaml
jobs:
build-and-push:
runs-on: ubuntu-latest
permissions:
contents: write # 🔒 Required for the GitOps commit step
steps:
# … [Build and Push Steps] …
– name: Update Helm Chart Image Tag & Commit
run: |
git config –global user.name “GitHub Actions Bot”
git config –global user.email “[email protected]”
sed -i ‘s/tag: .*/tag: “${{ github.sha }}”/’ ./services/ai-inference/chart/values-prod.yaml
git add ./services/ai-inference/chart/values-prod.yaml
git commit -m “chore(gitops): update image tag to ${{ github.sha }} [skip ci]”
git push origin main
When GitHub receives the push, its engine parses the commit message. Registering skip ci halts CI workflow re-evaluation, allowing GitOps controllers like Argo CD to detect the updated tag in values-prod.yaml and sync the Kubernetes cluster state safely.
Takeaway #6: Multi-Tiered Semantic Caching Slashes Latency and Prevents Model Burnout
Foundation model inference is the primary compute bottleneck and cost driver in AI systems. A two-tiered caching engine built into the ingress AI gateway can intercept repetitive or semantically equivalent queries, serving cached completions in milliseconds while completely bypassing downstream model execution.
Multi-Tiered Semantic Caching Pipeline
 ┌───────────────────────────────────────┐
 │       Incoming Request Payload        │
 └──────────────────┬────────────────────┘
                    │
                    ▼
 ┌───────────────────────────────────────┐
 │ Tier 1: Exact SHA-256 Hash Cache      │
 └──────────────────┬────────────────────┘
                    │ (Hit: <5ms) ──► Return Cached Completion
                    │ (Miss)
                    ▼
 ┌───────────────────────────────────────┐
 │ Tier 2: HNSW Vector Semantic Cache    │
 └──────────────────┬────────────────────┘
                    │ (Similarity ≥ 0.95: <20ms) ──► Return Cached Completion
                    │ (Miss)
                    ▼
 ┌───────────────────────────────────────┐
 │ Downstream Foundation Model Inference │
 └───────────────────────────────────────┘
Would you like to review or explore any other sections of the document?
Layer 1 (L1): Exact-Match Key-Value Cache
Incoming request payloads are canonicalized by stripping non-semantic variables (such as trace IDs, client timestamps, and system headers). The gateway computes a SHA-256 cryptographic hash over the canonical JSON string and executes an $O(1)$ lookup in Redis.
- Latency: $< 5\text{ ms}$
- Accuracy: Zero false positives.
Layer 2 (L2): Vector Semantic Cache
If L1 misses, the query text is passed to a lightweight embedding model (text-embedding-3-small) to produce a normalized vector $\vec{q}$ . An approximate nearest neighbor (ANN) search across a Hierarchical Navigable Small World (HNSW) graph index compares $\vec{q}$ against stored prompt vectors $\vec{c}_i$ within the client’s isolated tenant namespace using Cosine Similarity:
$$\text{Cosine Similarity}(\vec{q}, \vec{c}_i) = \frac{\vec{q} \cdot \vec{c}_i}{\|\vec{q}\| \|\vec{c}_i\|}$$
If the maximum similarity score meets or exceeds a strict threshold ( $\theta$ ), the cached output is returned immediately ( $<20\text{ ms}$ latency).
Configuring $\theta$ requires balancing hit rates against accuracy. Setting $\theta < 0.90$ introduces semantic drift , matching queries with distinct operational context to incorrect answers. Setting $\theta > 0.98$ degrades cache utility back to exact-match levels. Maintaining a threshold of $\theta \ge 0.95$ eliminates context contamination while delivering high cache hit rates.
Conclusion: Moving from Monoliths to Modular Defense-in-Depth AI Systems
The failure modes detailed across these six takeaways demonstrate that scaling generative AI requires moving away from fragile, monolithic prompts and single-stage vector pipelines. Production maturity demands a transition to modular, compound AI microservices—decoupling core capabilities into independently deployable components:
- Data Ingestion & Processing Service: Strategic hierarchical document chunking, hybrid index generation (BM25 + Dense), and metadata enrichment.
- Model Abstraction Service (AI Gateway): Centralized ingress control enforcing multi-dimensional token-bucket rate limiting, dynamic payload reservations, L1/L2 semantic caching, and unified provider routing.
- Orchestration Service: Decoupled workflow execution governing retrieval pipelines, reciprocal rank fusion, and cross-encoder neural reranking.
- Memory-as-a-Service (MaaS): Centralized short-term session state and long-term memory management isolated from individual execution agents.
By structuring systems around these modular microservices, engineering teams can implement robust, defense-in-depth AI architectures governed by version-controlled GitOps automation:
- Retrieval Precision: Combine BM25 sparse keyword search with dense embeddings via Reciprocal Rank Fusion ( $k=60$ ), and refine candidates using cross-encoder neural rerankers with an initial pool depth of 50 candidates .
- Query Safety: Omit HyDE in factual or numerical domains where hallucinated pseudo-documents degrade vector matching.
- Ingress Stability: Protect model servers using token-bucket rate limiting with output token dynamic reservations and refunds to handle payload asymmetry.
- Pipeline Integrity: Secure GitOps deployment pipelines using explicit write clearances (contents: write) and skip ci circuit breakers.
- Latency Optimization: Deploy L1 exact SHA-256 hash caching alongside L2 HNSW vector semantic caching with similarity thresholds held at $\theta \ge 0.95$ .
Take a moment to audit your current AI stack against these production realities: Is your architecture relying on PoC shortcuts and unconstrained model calls, or is it backed by a modular, enterprise-grade defense-in-depth pipeline built for long-term reliability?