From Upstream Scoping to Disproof Architectures: Mastering the Art of Adult Research
Fri Oct. 23, 2026 /Mpelembe Media/ — Developing a high-rigor independent research capability requires replacing unstructured curiosity with deliberate structural frameworks designed for time-constrained professionals. Unstructured exploration routinely collapses under its own cognitive weight due to an expanding volume of information, making upstream scoping and strict bounding essential. Effective inquiry begins by tapping into an intrinsic curiosity engine and reframing broad topics into narrow, diagnostic queries that define what data is relevant and what can be safely ignored. Proposed research projects must pass a “So What?” significance filter to evaluate their intellectual yield, while adjacent curiosities are deferred to a dedicated backlog so execution momentum remains intact. Research depth is ultimately governed by a pre-defined deliverable, establishing a clear stopping mechanism and preventing open-ended documentation.
To accelerate analysis without succumbing to automation bias, investigators integrate inverse artificial intelligence workflows anchored in Charlie Munger’s inversion principle. Rather than using generative models to confirm consensus views or validate pre-existing hypotheses, negative-space prompting instructs Large Language Models to construct bear cases, identify operational red flags, and execute “kill-the-company” scenarios. This prompt architecture incorporates specific industry contexts, demands diagnostic domain metrics, and frames AI output as preparation for adversarial management reviews. While AI accelerates processing speed across financial statements and literature, critical synthesis and probability assessment remain strictly human responsibilities.
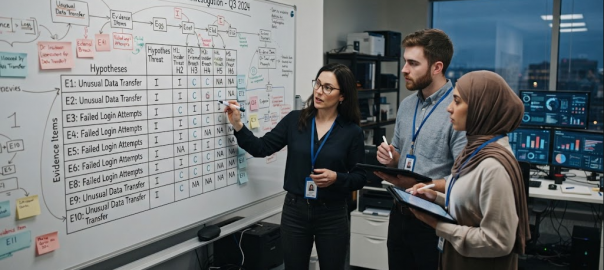
Falsification methodologies like the Analysis of Competing Hypotheses (ACH) serve as a primary safeguard against cognitive bias. Developed by Richards J. Heuer Jr. at the Central Intelligence Agency, ACH evaluates evidence against a set of mutually exclusive hypotheses within a comparative matrix. Unlike traditional analysis that accumulates supporting evidence for a favored view, ACH focuses on disproof by systematically identifying disconfirming evidence to eliminate unviable explanations. Evidence is evaluated based on its diagnosticity, prioritizing data points that actively discriminate between competing options. However, empirical evaluations of intelligence analysts indicate that ACH must be combined with sensitivity testing, as analysts often deviate from prescribed matrix steps and structured techniques can occasionally introduce judgment inconsistencies if data inputs are ambiguous.
Sustained intellectual productivity requires linking individual research projects to persistent knowledge management infrastructures. The Building a Second Brain methodology organizes information by actionability using the Projects, Areas, Resources, and Archives (PARA) structure alongside the CODE framework—Capture, Organize, Distill, Express. Progressive summarization distills captured material through multi-pass highlighting so core claims emerge quickly upon re-examination. To compound knowledge over longer horizons, concept-focused Evergreen notes and associative Zettelkasten networks connect ideas across domain boundaries, creating reusable building blocks that accelerate future creative output.
Together, these disciplines form an integrated six-stage analytical life cycle that spans scoping, scaffolding, ingestion, disproof, distillation, and expression. By structuring problem statements, leveraging inverse AI prompts, systematically evaluating evidence through disproof, and archiving insights into a compounding digital second brain, busy adults can consistently transform passive curiosity into actionable, high-value knowledge.
The Intelligence Paradox: Why the CIA’s Favorite Decision-Making Tool Backfires (And What to Do Instead)
Introduction: The High-Stakes Quest to Defeat Confirmation Bias
The struggle for objectivity is a defining challenge for intelligence agencies, corporate strategists, and high-stakes decision-makers alike. When evaluating complex, ambiguous information, even highly trained professionals frequently fall in love with an initial narrative. This cognitive trap leads analysts to practice selective search—collecting evidence that confirms their favored assumptions while filtering out disconfirming signals.
To combat catastrophic cognitive failures , Central Intelligence Agency (CIA) analyst Richards (Dick) J. Heuer Jr. developed the Analysis of Competing Hypotheses (ACH) in the late 1970s. Detailed in his landmark work Psychology of Intelligence Analysis , ACH was engineered as the flagship Structured Analytic Technique (SAT) designed to force analysts to systematically evaluate evidence against a full set of mutually exclusive possibilities. The method quickly became institutionalized across national security agencies, featuring prominently in official policy references such as the U.S. Government’s Tradecraft Primer and the UK Ministry of Defence’s Quick Wins for Busy Analysts handbook, before spreading widely into corporate competitive intelligence and strategic consulting.
A striking intelligence paradox has nevertheless emerged from modern decision science. Despite decades of widespread endorsement, empirical research reveals that ACH routinely fails in practice—and can actually increase judgment inconsistency, foster false rigor, and amplify decision errors.
Takeaway #1: The CIA’s Premier Debiasing Tool Can Actually Increase Errors
Empirical studies evaluating ACH on practicing intelligence professionals reveal a severe disconnect between theoretical design and operational execution. In a landmark 2019 study published by Mandeep K. Dhami, Ian K. Belton, and David R. Mandel, 50 trained intelligence analysts were evaluated on a probabilistic hypothesis-testing task. Half of the cohort was trained and instructed to execute ACH, while an untrained control group completed the task using unstructured reasoning.
The empirical results were striking: ACH-trained analysts routinely departed from the technique’s prescribed mechanics. Crucially, 80% of the ACH group failed to execute the core evidence integration rule (which requires identifying the leading explanation based solely on the fewest inconsistency ratings), opting instead to tally both consistent and inconsistent data. Furthermore, 80% of ACH users produced tied hypothesis rankings (compared to just 19% of control analysts), effectively destroying the tool’s capacity to yield actionable intelligence. Process execution was equally compromised: only 4% of ACH analysts applied their evidence scoring rules consistently across items, whereas 44% of control analysts who used scoring rules achieved operational consistency.
The researchers summarized these findings with a stark empirical warning:
“We found that ACH‐trained analysts did not follow all of the steps of ACH. There was mixed evidence for ACH’s ability to reduce confirmation bias, and we observed that ACH may increase judgement inconsistency and error.” — Mandeep K. Dhami et al.
Subsequent statistical breakdown of the experimental data reveals why this breakdown is so catastrophic: within-individual consistency is the primary mathematical driver of analytical accuracy. Analysts who consistently applied their evidence assessment rules were 8.89 times more likely to be accurate in selecting the correct outcome (McNemar test, odds ratio = 8.89, p = .021), and those who applied consistent integration rules were 2.21 times more likely to be accurate (odds ratio = 2.21, p < .001).
From a cognitive systems perspective, traditional SATs suffer from a fundamental architectural flaw: they attempt “unipolar debiasing”—targeting a single bias like over-confidence—without recognizing that heavy manual tradecraft induces execution friction. By forcing analysts to process cognitive loads beyond working memory capacity, manual matrices trigger response-threshold shifting and mirror-image “bipolar” biases, such as extreme under-confidence and systemic tied rankings. Inconsistency is not an aesthetic flaw; it is the direct mathematical engine of analytical error.
Takeaway #2: True Rigor Means Counting Disproof, Not Accumulating Proof
Despite its operational shortcomings, ACH popularized an essential epistemological principle drawn from Karl Popper’s falsificationism: true analytical rigor requires actively disproving hypotheses rather than accumulating supporting evidence. Standard ACH shifts the foundational question from “What evidence proves my favorite theory?” to “Which hypothesis is least inconsistent with the facts?”
Central to this logic is the concept of diagnosticity . Information that is consistent with every potential explanation exhibits zero diagnosticity—it is mere background noise. Analysts frequently fall prey to pseudo-diagnosticity , mistaking an abundance of consistent evidence for proof, when in reality evidence is only diagnostic if it possesses the power to isolate and eliminate competing explanations.
To enforce a disconfirmation mindset, decision-makers must fundamentally alter how they navigate an evaluation grid:
- Proving a Preference (Working Down): Examining one favored hypothesis vertically against all facts. This orientation encourages analysts to cherry-pick confirming evidence, rationalize away contradictions, and reinforce pre-existing biases.
- Eliminating Inconsistencies (Working Across): Evaluating a single piece of evidence horizontally across all competing hypotheses simultaneously. This horizontal evaluation tests which specific theories the fact actively contradicts, systematically eliminating options that fail the test of evidence.
Takeaway #3: The “Decomposition” Trap Creates False Rigor and Base-Rate Neglect
A structural failure of ACH lies in its reliance on massive problem decomposition—breaking complex scenarios into extensive rows of evidence and columns of hypotheses. While neat visual matrices give decision-makers an impression of thoroughness, they frequently construct a dangerous illusion of “false rigor.”
Forcing continuous probabilistic data onto rigid, coarse ordinal scales (such as binary tags or 5-point consistency ratings) strips away vital nuance. This artificial flattening creates artificial clusters of tied ranks and masks flawed reasoning behind structured cell scores, bestowing undeserved confidence on fragile conclusions.
Even more glaring is ACH’s structural vulnerability to base-rate neglect . The standard ACH matrix provides no mathematical mechanism for incorporating prior probability distributions—the baseline frequency of an event occurring before new evidence is introduced. By simply counting cell inconsistencies without multiplying by prior probabilities, ACH forces an implicit uniform prior assumption .
Consider the experimental task evaluated by Dhami et al., set in the fictional Zuma region with four distinct tribes: Acanda (5% base rate), Bango (20%), Conda (30%), and Dengo (45%). By treating every hypothesis column as starting from an identical baseline, ACH treats a 5% prior probability as mathematically equivalent to a 45% prior probability. In real-world environments with highly skewed base rates—such as low-probability/high-impact strategic warnings—this structural omission systematically blinds decision-makers to reality.
As argumentation theorist Tim van Gelder highlights, ACH treats hypotheses as a “flat list” of isolated options. It fails to capture hierarchical relationships, argument dependencies, or subordinate logic supporting individual items of evidence. By demanding dozens or hundreds of discrete, low-value judgments, complex matrix decomposition leaves human minds disoriented, fatigued, and prone to error.
Takeaway #4: Simple Statistical Cleanups Beat Complex Manual Matrices
While labor-intensive manual matrices overload human cognition, judgment and decision science points toward a vastly superior alternative: simple statistical recalibration and aggregation.
In empirical evaluations directly comparing analytical correctives, mathematical post-processing consistently outperforms complex manual frameworks. Research led by David R. Mandel, Christopher W. Karvetski, and Mandeep K. Dhami demonstrates that probability judgments can be dramatically improved without forcing analysts through cumbersome manual steps. By taking analysts’ raw probabilistic estimates, mathematically “coherentizing” them—adjusting estimates to ensure they strictly respect the unitarity axiom of probability theory—and aggregating them across individuals, judgment error collapses.
Mean absolute error (MAE) in probability judgments decreased by 61% simply by coherentizing estimates and aggregating them across analysts.
This 61% error reduction highlights a vital principle for organizational design: enforcing mathematical coherence eliminates noise and subadditivity (the human tendency for uncalibrated sub-component probabilities to sum to far greater than 100%) far more effectively than manual scoring grids. Rather than forcing human analysts to act as subpar manual calculators, high-performing decision systems collect light-touch probabilistic estimates and apply rigorous statistical recalibration behind the scenes.
Takeaway #5: Modern Debiasing Requires Light-Touch Workflows and Inverse AI
Modern cognitive systems design is shifting away from heavy manual matrix tradecraft toward light-touch psychological interventions and automated cognitive scaffolding.
At the individual level, targeted psychological prompts achieve robust debiasing without cognitive fatigue. The “Consider-the-Opposite” intervention (Lord, Lepper, & Preston, 1984) explicitly instructs analysts to evaluate how they would react if key evidence pointed in the reverse direction, or forces the evaluation of explicit complement queries (“What is the probability of X versus not X?”). Similarly, gamified debiasing interventions—such as interactive single-session training games (Morewedge et al., 2015)—have been shown to significantly diminish confirmation bias immediately, maintaining measurable debiasing effects months after exposure.
At the organizational level, high-rigor environments are integrating Inverse Artificial Intelligence scaffolding . Standard generative AI integration often accelerates confirmation bias, as users prompt Large Language Models (LLMs) to summarize consensus viewpoints or validate executive intuition. Inverse AI, by contrast, deploys LLMs as deliberate adversarial engines engineered to challenge human assumptions.
For example, rather than asking an LLM to “summarize the evidence for Strategy A,” an Inverse AI prompt workflow instructs the model:
“Assume my leading hypothesis is completely wrong. Generate 3 hidden assumptions required for it to be true, identify missing diagnostic evidence that would disprove it, and construct the strongest possible argument for the opposite outcome.”
Traditional Manual ACH,Light-Touch Cognitive & Automated Cleanups
Workflow Burden,Demands exhaustive manual matrices and hundreds of discrete cell ratings.
Probability Mechanics,”Ignores prior probabilities, forcing uniform priors and base-rate neglect.”
Data Scaling,”Forces continuous data onto coarse ordinal scales, causing tied hypothesis ranks.”
Technological Integration,Relies on manual grids; risks AI confirmation loops when using standard LLM prompts.
Conclusion: Upgrading Your Mental Tradecraft
Improving decision quality under extreme uncertainty is not about filling out exhaustive matrices or spending hours scoring spreadsheet cells. Overly complex manual tradecraft creates an illusion of rigor while introducing cognitive friction that increases judgment inconsistency and error.
True analytical tradecraft relies on disciplined disconfirmation, light-touch cognitive prompts, simple statistical aggregation, and automated adversarial stress-testing.
To protect your strategic decisions against confirmation bias, evaluate your organizational analytical system with a single question: Are you actively leveraging statistical cleanups and adversarial scaffolding to disprove your assumptions, or are you simply building neater matrices to justify what you already believe?